What Is a Canonical Tag?
Understand how rel=canonical identifies a preferred URL among duplicate or very similar versions without acting as a redirect.
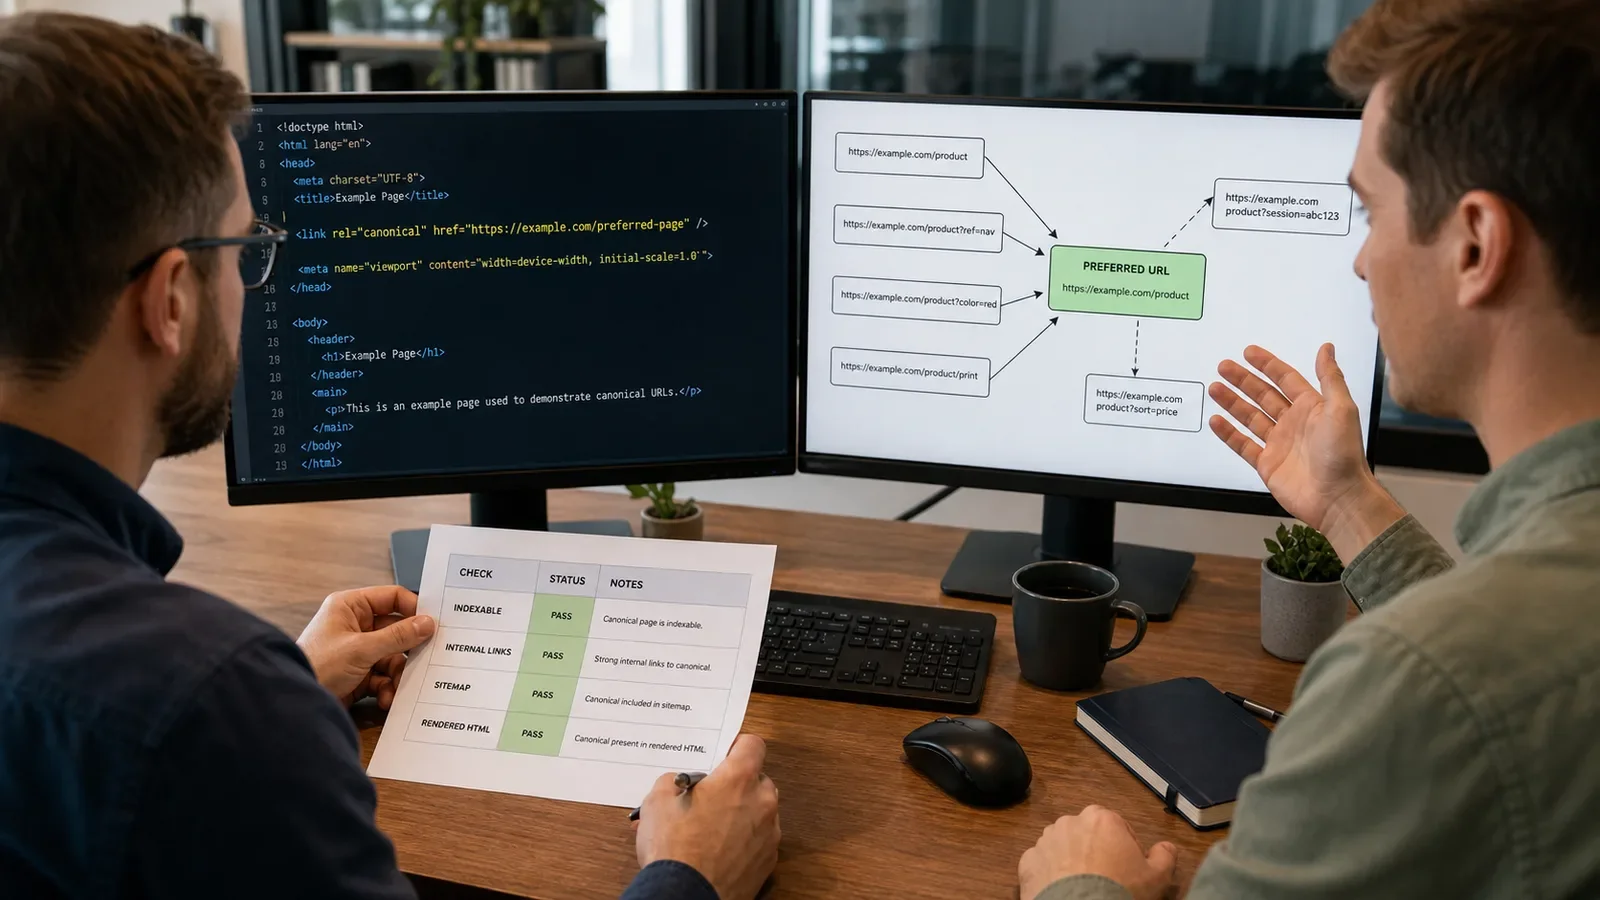
A canonical tag is an HTML link element that identifies the preferred URL for a page when the same or very similar content can appear at more than one URL. It uses `rel="canonical"` and an absolute destination URL in the page head.
The tag is a signal to search engines, not a command and not a redirect. Visitors can still open the duplicate URL. Search systems may choose another canonical when redirects, internal links, sitemaps, content, and tags send conflicting signals.
Put It in Plain Words
One page can have more than one web address. A shop page may have a clean address. The same page may also open with a filter or tracking code in the address.
A canonical tag says which address you want search tools to treat as the main one. The tag sits in the page code. It points to the full address of the main page.
The other address still works. A person who opens it does not move to a new page. This is why a canonical tag is not the same as a web redirect.
Search tools read more than the tag. They also see links, maps, page text, and redirects. If those signs do not agree, the tool may pick a different main page.
Use the tag only for the same page or a very close copy. Do not point ten different service pages to one page. That hides the real shape of the site.
Make sure the target works. It should not be a draft, error, or blocked page. Use the live site name. Do not send a live page to a test site by mistake.
Link to the main address from the rest of the site. Put that address in the site map. Keep all the signs clear and in line.
After a change, check the code that a search tool can see. Then use Search Console to see which main page Google chose. The tag is a request, not a rule Google must obey.
Here is a plain case. A page can open with a code at the end of its web address. That code may tell a shop which ad sent the visit. The page text stays the same.
The clean address can be the main one. The coded copy can point to it. Links in the site should also use the clean form when they can.
A print view can work the same way. A person may need it, so you keep it live. The print view can point to the full page as the main copy.
A moved page is a new case. If the old page should send all people to the new one, use a redirect. That is more clear for both people and search tools.
A page you do not want in search is also a new case. A noindex tag asks search tools to leave it out. It does not pick the main page in a set.
Do not block a copy before the search tool can read its tag. The tool may see the address but miss the hint in the page code.
Check for loops. Page A should not name Page B while Page B names Page A. Check for chains too. The main page should be the final live page.
Check each language on its own. The main page for French text should be a French page when one exists. Language links have a different job from the main-page tag.
Check the page on the live site. A tag in a test build does not prove the live tag is right. View the source and the final page made by scripts.
Keep a small list of rules for each page type. Product filters may use one rule. News pages may use another. Test each rule with a real URL.
When Google picks a new main page, do not change tags at once. First find which signs do not match. Fix the root cause and check again.
How Does Canonical Tag Work?
Suppose a product page is reachable through a clean URL and several tracking or filter URLs. Each duplicate can point to the clean version. The preferred page can also point to itself with a self-referential canonical.
Search engines combine this signal with redirects, sitemap URLs, internal links, content similarity, and other evidence. When the preferred version is accepted, search systems can focus indexing and signals on that URL instead of treating every variation as a separate main page.
Why Is It Important?
Canonicalization can reduce confusing duplicate versions, consolidate signals, make reporting clearer, and help search engines spend more time on useful pages. It is especially important on sites with filters, parameters, print versions, syndication, ecommerce variants, or several URL paths to the same content.
It does not rescue unrelated or poor pages. Canonical targets should be genuine duplicates or close equivalents. If a page has moved permanently, a redirect is usually clearer because it also sends users to the new URL.
Where Is It Used?
HTML pages through a link element in the valid head of the document.
Non-HTML files such as PDFs through a supported HTTP Link response header.
Ecommerce filters, tracking parameters, print pages, syndicated content, and URL migrations.
Multilingual or regional systems alongside correct hreflang, using a canonical in the same language where possible.
A Canonical Tag Example
If `https://example.com/services/branding` is the preferred page, a duplicate parameter URL can include `<link rel="canonical" href="https://example.com/services/branding" />` in its head. The preferred page can include the same element pointing to itself.
Use the full production URL. Do not point the live page to staging, a broken page, a blocked page, or a different topic. Check the rendered HTML and Google-selected canonical in Search Console after release.
What Makes a Canonical Implementation Clear?
One absolute, indexable, final-status URL that represents the same or very similar content.
A valid link element in the HTML head or a correct HTTP Link header for a non-HTML file.
Consistent redirects, internal links, hreflang, structured data, and sitemap inclusion.
A self-referential canonical on the preferred page when the site can support it reliably.
No chain, loop, fragment target, staging host, or contradictory canonical method.
How Do You Audit Canonical Tags?
Crawl every indexable URL and record status, canonical destination, and whether the target is indexable.
Group duplicate or near-duplicate pages and decide which URL should represent each group.
Compare canonical tags with redirects, internal links, sitemaps, hreflang, and structured data.
Check rendered HTML so client-side code does not replace a correct server value.
Inspect important URLs in Search Console and investigate declared versus selected differences.
Retest after templates, filters, pagination, migrations, or domain settings change.
Canonical Tag vs. Redirect vs. Noindex
A canonical tag keeps a duplicate page available while suggesting another URL for search. A redirect takes users and crawlers to a different URL and is a stronger consolidation signal. `noindex` asks search systems not to index that page; it is not the preferred way to choose one canonical within a duplicate group.
Robots.txt controls crawling, not canonical selection. Blocking a duplicate can prevent a crawler from seeing its canonical tag. Choose the control that matches the real purpose instead of stacking contradictory instructions.
Common Mistakes
Pointing every page in a category to one page even though their content differs.
Using a relative, malformed, redirected, blocked, noindexed, or non-200 target.
Sending one canonical in HTML and a different one through another method.
Keeping internal links and sitemaps focused on duplicate URLs.
Assuming the declared canonical must become the search engine’s selected version.
Frequently Asked Questions
Does every page need a self-canonical?
Google recommends a self-referential canonical on the canonical page. It can make the preferred URL explicit and protect against some accidental variants, but the whole signal set still needs to agree.
Can a canonical point to another domain?
Cross-domain canonicals can be used for matching syndicated or duplicate content, but the target must truly represent the content and both publishers should understand the effect.
Why did Google choose a different canonical?
Common causes include stronger redirects or links, inconsistent sitemaps, materially different content, weak or broken targets, rendering changes, and conflicting signals. Use URL Inspection and a full signal audit.
For the wider system, read Canonicalization for SEO and Does Removing a Page From a Sitemap Remove It From Google?.
Need to untangle conflicting index signals?
Book a free Brand and Tech Assessment to map the current problem, evidence, constraints, and practical next step.
Sources
- Google Search Central: Specify a Canonical URL. https://developers.google.com/search/docs/crawling-indexing/consolidate-duplicate-urls
- Google Search Central: SEO Starter Guide. https://developers.google.com/search/docs/fundamentals/seo-starter-guide
- IETF RFC 6596: The Canonical Link Relation. https://www.rfc-editor.org/rfc/rfc6596