What Is Retrieval-Augmented Generation?
Learn how RAG retrieves source material for a language model, where grounding can fail, and why permissions, citations, evaluation, and ownership matter.
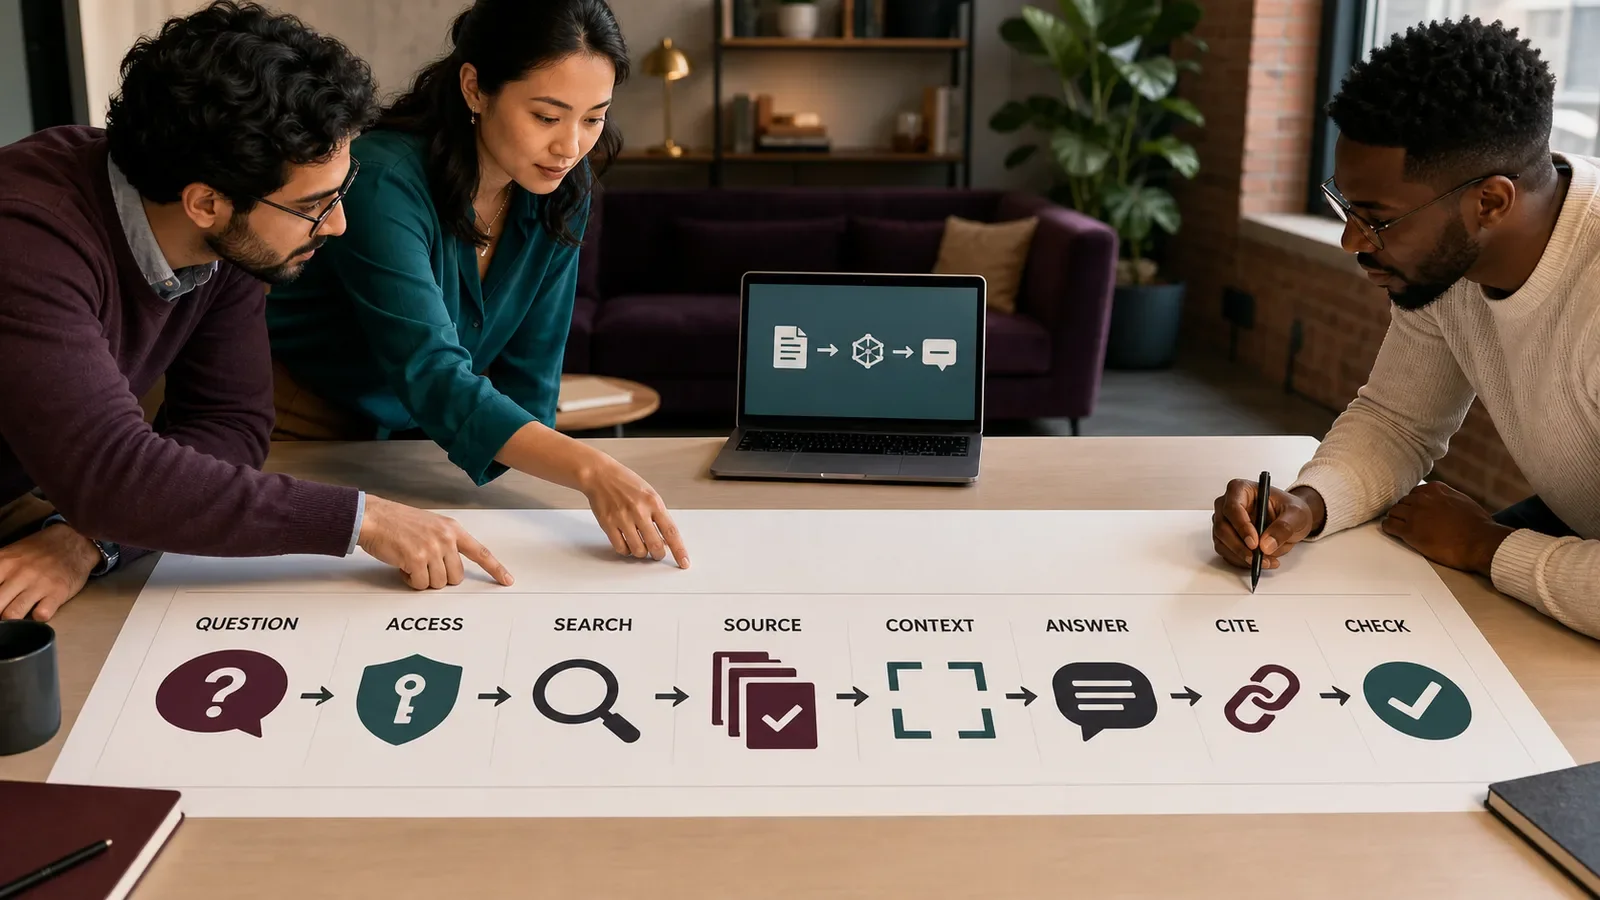
Retrieval-augmented generation, or RAG, is a method that retrieves information after a model was trained and supplies that material as context for generated output. It combines a retrieval system with a generative model.
RAG can help a model use current, private, or task-specific sources without putting all of that knowledge into the model parameters. It does not guarantee that retrieval, interpretation, citations, or answers are correct.
Put It in Plain Words
A user asks a question. The application may rewrite or classify it before search.
The retrieval step searches an approved collection and selects passages, records, or other items that appear relevant.
The system places some of those items in the model context with instructions for how to use and cite them.
The model generates an answer from the prompt, retrieved context, learned parameters, and settings.
A poor search can miss the right source. A strong search score does not prove that a passage answers the question.
Chunks can split a key limit from its rule, table, date, heading, or exception. Store enough structure to rebuild meaning.
Apply permissions before retrieval and again before display. A model must not reveal a document merely because it can find it.
Treat retrieved text as untrusted input. A document can contain instructions that try to redirect the model or expose data.
Check each citation against the claim it appears to support. A real link can still be irrelevant or contradict the answer.
Keep the source owner, update time, index version, model, prompt, evaluation set, and incident path. RAG quality changes when any part changes.
A Quick Check Before You Use It
Start with a small set of sound source files.
Give each file an owner.
Mark the date each rule starts and ends.
Remove old drafts from the live set.
Keep page titles and heads with the text.
Keep each note close to its key rule.
Do not split an exception from the rule it limits.
Apply each user right before the search.
Apply the same right before the reply is shown.
Use a test set with known answers.
Add asks that have no answer in the files.
Add asks where two files clash.
Ask the tool to say when no source is enough.
Make each link point to the true source.
Open each link and read the cited part.
Check that the cited part backs the claim.
Do not show a file the user may not see.
Treat all source text as untrusted input.
Keep the search rule and model name.
Keep the index date and test date.
Log a bad answer and the source that led to it.
Fix the root file when the root file is wrong.
Run all tests after a source or tool change.
Name the person who can stop the system.
Ask one fact in two ways.
Ask for a rule and its key limit.
Ask for a date from an old and new file.
Ask for a fact that the user may not see.
Check the safe no-answer case.
Check the case where search finds no text.
Check the case where search finds too much text.
Check that a bad file cannot give a new command.
Keep a list of all live source sets.
Remove a file when its owner says it is void.
A source link does not make a claim true.
How Does Retrieval-Augmented Generation Work?
The system prepares source content, builds an index or search layer, retrieves items for a query, and adds selected context to a model request. The model then generates an output that may include source links.
Teams can use keyword, vector, graph, database, or mixed retrieval. The right method depends on the content, permission model, task, latency, update need, and type of question.
Why Is It Important?
RAG can connect an LLM to material that is newer, narrower, or private. It can also make source inspection and updates easier than retraining a model for every document change.
It adds a chain of failure points: source quality, parsing, chunks, permissions, query, ranking, context, generation, citation, and display. Each part needs tests.
Where Is It Used?
Knowledge assistants, support, research, policy lookup, and document Q&A.
Product help, staff portals, legal or compliance research support, and technical search.
Current-data summaries, source-linked drafting, and controlled private collections.
A Simple RAG Example
A staff assistant searches approved policy pages that each have an owner, effective date, access rule, and canonical URL. It sends the best passages with the question to an LLM.
The answer quotes no private data, links each policy claim, and says when the sources conflict or do not answer. A person handles high-risk decisions and corrections.
What Should a RAG System Record Include?
Task, users, risk, answer scope, and owner.
Source collection, owner, rights, status, and update rule.
Parser, chunks, metadata, index, filters, and permissions.
Query, retrieval method, ranking, context, and limits.
Model, prompt, citations, output checks, and refusal behavior.
Evaluation set, logs, incidents, corrections, and retirement.
How Do You Build and Test RAG?
Choose a narrow task and approved source set.
Clean sources and preserve ownership and structure.
Apply access before indexing, retrieval, and display.
Build retrieval and require traceable citations.
Test search, answer, citation, privacy, and edge cases.
Monitor source and system change, then re-evaluate.
RAG vs. Fine-Tuning
RAG supplies retrieved context at use time. Fine-tuning changes model behavior by further training it on examples or data.
RAG is often useful when sources change or need citations. Fine-tuning can help with style, form, or repeated behavior. A system can use both, and neither removes source and task evaluation.
Common Mistakes
Indexing documents with no owner or access model.
Splitting content without headings, dates, or exceptions.
Calling a retrieved answer verified by default.
Showing citations without checking claim support.
Measuring only search or only generation.
Frequently Asked Questions
Does RAG stop hallucinations?
No. It can ground output in retrieved material, but retrieval and generation can both fail. Require sources, tests, and a safe response when evidence is missing.
Does RAG need a vector database?
No. Retrieval can use keyword search, a relational database, a graph, vectors, or a mixed system. Choose from the task and source structure.
Can RAG use private documents?
Yes, if the system enforces valid purpose, permissions, privacy, retention, and display rules. Index access alone must not grant user access.
Use Fine-Tuning vs RAG for architecture tradeoffs and AI Assistants Cannot Fix Poor Documentation for the source-quality limit.
Need a RAG plan that tests the source, permission, retrieval, answer, and citation as one system?
Book a free Brand and Tech Assessment to map the current problem, evidence, constraints, and practical next step.
Sources
- Lewis et al.: Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. https://arxiv.org/abs/2005.11401
- Google for Developers: Machine Learning Glossary, retrieval-augmented generation. https://developers.google.com/machine-learning/glossary